We Already Have LLMs. Why Does Jev Exist?
Jev answers predefined questions with choices, scores and probabilities. Here is how that differs from a structured-output LLM.
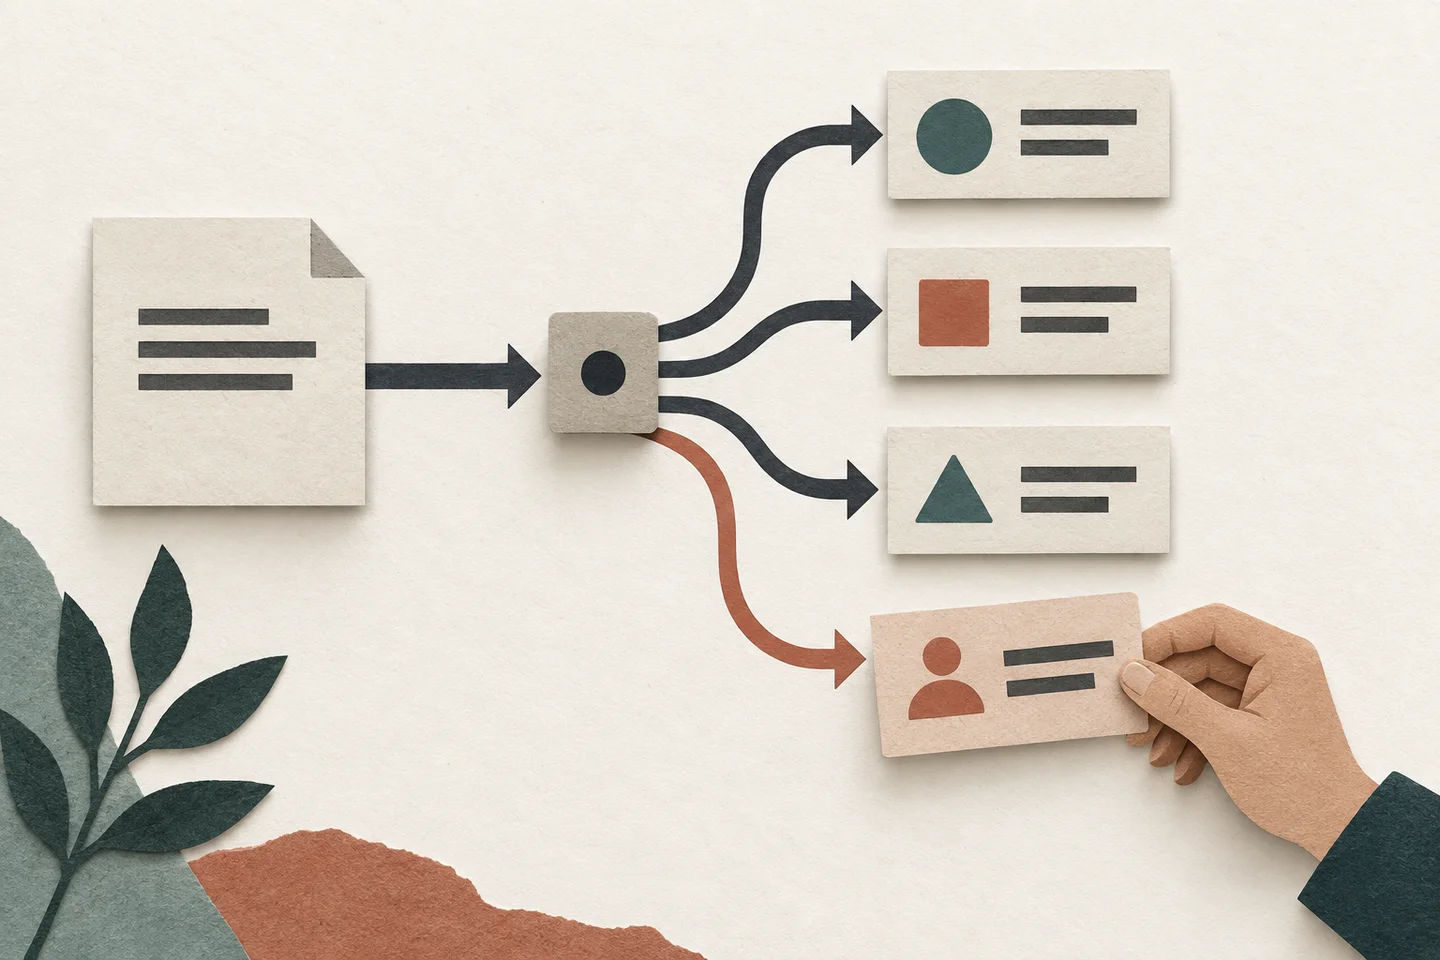
AI-generated conceptual illustration. This is not a Jev product screenshot.
Jev is a decision model from TypeSafe. The developer defines the questions. Jev returns a choice, a score or a yes probability that application code can use. Modern LLMs can do the same jobs, but Jev is designed around this narrower role.
Route a refund request
Suppose a customer writes:
I was charged twice and I want my money back.
A support classifier only needs to decide which team should receive the request.
The developer defines the possible answers first, such as refund, explain_charge and other. Jev selects one. Ordinary code handles the next action.
The object and 0.96 below are invented for explanation. They are not the result of a live Jev call or a TypeSafe SDK shape. The value does not mean 96 per cent accuracy.
// Hypothetical application adapter, not a TypeSafe SDK signature.
const supportDecision = {
  category: 'refund',
  confidence: 0.96,
};

if (supportDecision.category === 'refund' && supportDecision.confidence > 0.9) {
  routeToRefundTeam();
} else {
  sendToHumanReview();
}
The AI classifies the request. It does not issue the refund or choose the 0.9 cutoff. Application code decides whether to automate the action or send it to a person. The cutoff is also illustrative and needs testing on the application’s own data.
unstructured input
        ↓
bounded AI decision
        ↓
probabilities and confidence
        ↓
ordinary if/else code
How this differs from a structured-output LLM
Current LLM APIs also support JSON schemas, tool calls and constrained output. OpenAI’s Structured Outputs guide says supported models can follow schemas containing basic types and nested objects.
Older prompt-only integrations could produce malformed JSON, such as an invalid trailing comma. Current structured-output features greatly reduce that problem. The output may still be wrong in meaning, and a model may refuse the request.
Jev’s output range is narrower. Its public API offers three decision types: Choice, Score and Noul. For these decisions, it also returns probabilities for the available options.
Scroll horizontally to view every column on a small screen.
| Question | Jev | Structured-output LLM |
|---|---|---|
| Output range | Choice, Score or Noul | A supported JSON Schema |
| Free strings and nested objects | Cannot generate them directly | Supported |
| Probabilities for alternative answers | Returned for bounded Choice and Score decisions | Usually not part of schema conformance itself |
| Generate an explanation or reply | No | Yes |
| Can be correct in shape but wrong in meaning | Yes | Yes |
A structured-output LLM covers more ground when the application needs a flexible response, complicated reasoning, conversation or information whose possible values cannot be listed in advance. Jev may be more direct when the valid answers are known and their probabilities change what the application does next.
The three answers Jev can return
TypeSafe’s public HTTP API receives the content to evaluate as state, along with a model name and questions. state can be a string, object or array. The documented model name is jev-latest.
Each question uses one of three formats:
-
Choice selects one label from a list supplied by the developer. It returns the selected label, a probability for every label and confidence. The Choice documentation allows up to 255 labels.
-
Score evaluates the input against ordered levels described by the developer. The Score documentation says it returns a probability for each level, a probability-weighted score, descriptions of the levels and confidence. The weighted result can be fractional even when the levels use integers.
-
Noul answers a yes-or-no question with a number from 0 to 1. That number is the probability of “yes”. According to the Noul documentation, it does not have a separate confidence field.
Jev does not offer a general “fill any JSON Schema” output. It cannot directly generate a free string, an arbitrary nested object or an unrestricted number.
TypeSafe’s date extraction example follows the same boundary. Jev chooses date parts, then ordinary code checks the result.
High confidence can still be wrong
A Choice result contains a probability for every option. If the options are refund, explain_charge and other, the response includes three probabilities. Together, those values form a probability distribution.
Choice and Score also return confidence. TypeSafe’s confidence guide describes it as a summary of how clearly the probabilities concentrate on one option.
The fields answer different questions:
- Confidence is not the same value as the highest option probability.
- Confidence is not the probability that the answer is correct.
A high-confidence answer can still be wrong. The 0.96 above and 0.98 below are invented confidence values, not measurements.
Whether predicted probabilities match real outcomes is assessed across groups. If predictions given probability 0.8 are well calibrated, about 80 per cent of that group should be correct. It gives no certainty about one prediction. The scikit-learn calibration guide explains the same group-level distinction.
TypeSafe advises teams to test automation cutoffs on their own data. In the material reviewed for this article, I did not find public evidence showing how well Jev’s probabilities match outcomes in different domains.
TypeSafe says Jev cannot hallucinate. Its benchmark description also says the reported zero per cent hallucination or type-error figure is not empirical. An accepted response stays within the declared type and labels, yet Jev can still select a valid answer that is wrong.
A transaction-classification example
Consider this bank transaction description:
UBER *TRIP HELP.UBER.COM AUAn application could define five categories:
transport | food | accommodation | transfer | unknownThe result and 0.98 below are invented. They are not a live Jev result or an SDK call shape. High confidence does not guarantee a correct category.
// Hypothetical application adapter, not a TypeSafe SDK signature.
const transactionDecision = {
  input: 'UBER *TRIP HELP.UBER.COM AU',
  category: 'transport',
  confidence: 0.98,
};

if (transactionDecision.confidence > 0.9) {
  saveAutomatically(transactionDecision.category);
} else {
  sendToHumanReview();
}
A real financial application would need to consider the cost of a wrong category, review capacity and error rates for different transaction types. The automation cutoff may need to change with the risk of the decision.
What “System One Model” means
TypeSafe calls Jev the first System One Model. Its launch post says Jev outputs all probabilities in parallel instead of generating one token after another. TypeSafe also says it uses a parallel sampler and Reinforcement Learning for Calibrated Decisions, or RLCD. Its machine-learning primer describes Jev as returning decisions and probabilities instead of text.
These are vendor descriptions. In the material reviewed for this article, I did not find a paper, model card, weights, model size, input-length limit or training-data description. There was also not enough information to determine whether the internal network is a Transformer or another design. “Non-autoregressive” alone does not reveal that architecture.
Documented and proposed uses
Documented examples need to be separated from vendor proposals and hypothetical uses. An example in the documentation does not establish production accuracy or throughput.
Scroll horizontally to view every column on a small screen.
| Use case | Status and boundary |
|---|---|
| Customer-support routing | Documented in TypeSafe’s intent-routing pattern and customer-service evaluation |
| Transaction classification | Hypothetical. It fits Choice, but the bank example above is not a TypeSafe demo |
| Fraud-risk categorisation | Vendor-proposed. The use-case map describes fraud indicators and risk scoring. Domain testing is required |
| Content moderation | Documented in TypeSafe’s Choice consistency example |
| Lead scoring | Vendor-proposed in the use-case map. This is not validated product performance |
| Intent classification | Documented in TypeSafe’s intent-routing pattern |
| Document classification | Documented in TypeSafe’s hierarchical-classification example |
| LLM output verification | Documented in TypeSafe’s citation-checking and LLM-guardrail examples |
| Workflow routing | Documented through TypeSafe intent routing and confidence-based branching |
| High-volume background processing | Vendor-proposed in the use-case map. Production throughput is unverified |
The official examples include intent routing, moderation, hierarchical classification, citation checking and LLM guardrails. TypeSafe’s use-case map proposes additional applications.
What to check before adopting it
A team can compare Jev with a smaller structured-output model, a conventional classifier, embeddings or explicit rules. Scikit-learn’s text-classification example shows a conventional approach. Embeddings can support similarity search and vector-based classification. The comparison should include model calls, retries, human review, data preparation and operating cost.
TypeSafe’s evaluation site claims low cost and latency. TypeSafe wrote the cases, and the reference probabilities were model-generated. The launch post also acknowledges possible bias from case design and routing. In the official and open-source material reviewed, I did not find an independently reproduced benchmark.
As of 16 September 2026, Jev is an early-access service that requires an API key. The product and API documentation reviewed did not establish numeric rate limits, a service-level agreement, data-retention terms, deployment options, a maximum state size or an input-length limit.
Jev may fit when the valid answers are known before the request and their probabilities change the next action. It does not fit summarisation, conversation, code generation or extraction where the possible answers cannot be listed. Longer reasoning tasks must be split into smaller questions and joined again in application code, which adds development work.
Before adoption, compare Jev, a structured-output LLM, a smaller model, a conventional classifier, embeddings and rules on the same labelled cases. Measure the error rate, human-review load and cost, then prepare a fallback for failures.
Comments
Comments require JavaScript. The article remains available without it.